Article Scraper for Text, Authors, and Dates













Collect article data across changing page layouts
Read fields by meaning, schedule repeat runs, and use the same workflow across public websites.
Adapt when article layouts change
Thunderbit reads visible headlines, bylines, dates, summaries, and article text by meaning. The workflow depends less on fixed page positions when a news site changes its layout.
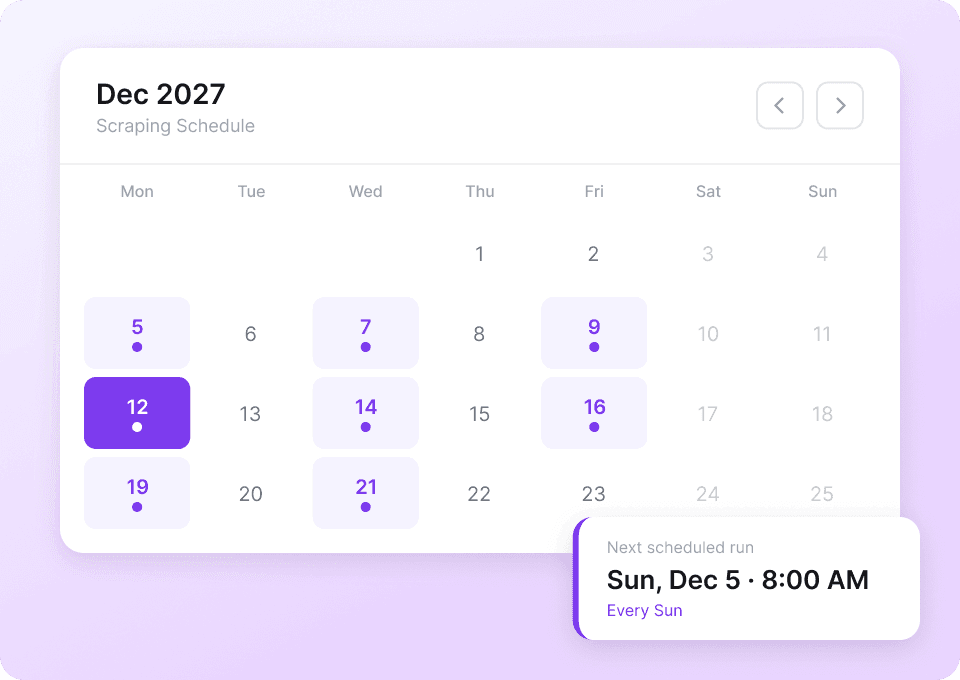
Run the article scrape on schedule
Set a repeat run for a public news, blog, or section page you revisit. Thunderbit can collect the latest visible articles and send new rows to your chosen file or app.
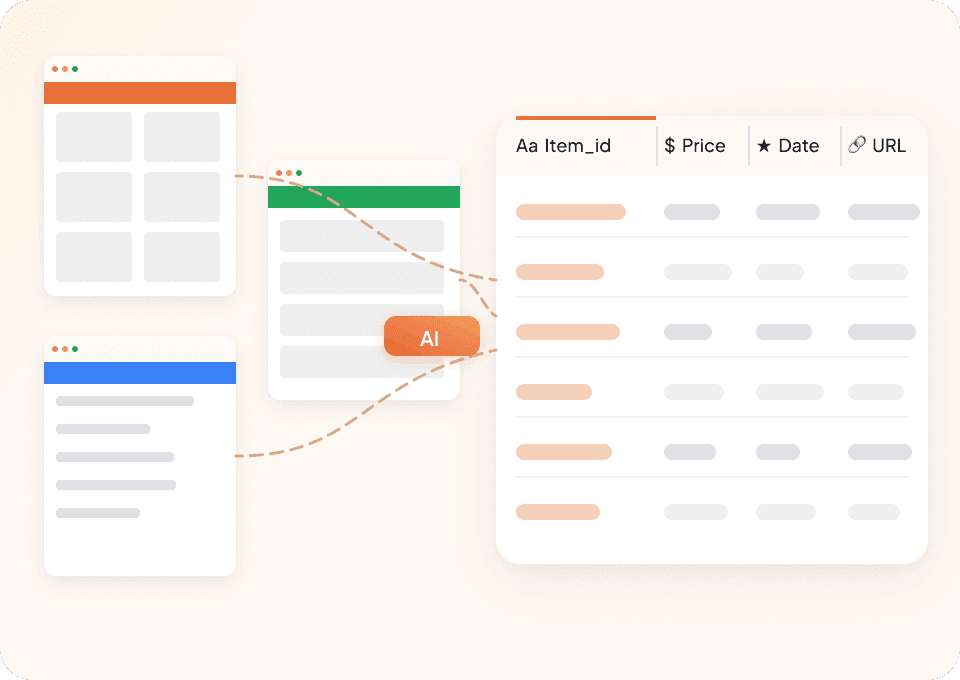
Use one workflow on any public site
Use the same workflow on any public site with articles. Name the fields you need, then let Thunderbit place each page in the same columns.
One article workflow across different page layouts
Fixed selectors follow positions. Thunderbit AI looks for the article fields you named.
A selector map for every publisher
Each page design needs separate upkeepArticle fields organized by Thunderbit
The requested record stays consistentWhat data can you extract from an article?
Choose from 30 visible content, author, publisher, date, link, topic, media, and page metadata fields.
- Headline
- Alternative Headline
- Article Body
- Article Summary
- Author Name
- Author URL
- Author Organization
- Publisher Name
- Publisher URL
- Date Published
- Date Modified
- Article Section
- Keywords
- Word Count
- Language
- Canonical URL
- Main Entity URL
- Image URL
- Image Caption
- Image Credit
- Video URL
- Audio URL
- Dateline
- About Topics
- Mentions
- Citation Links
- License URL
- Related Article Links
- Page Title
- Meta Description
Hear editors and research teams discuss article data
In these user videos, editors and researchers gather article text, bylines, dates, and source links for review.
Questions about scraping public articles
News sites use different layouts and page details, so the fields you get depend on the article page you capture.
Continue from articles to the pages around them
Explore news, author, and publisher scrapers when your research also needs indexes, profiles, or related stories.
MIXI Scraper
The Thunderbit MIXI Scraper lets you extract data from MIXI news listings and community ranking pages. Use AI-powered field suggestions to quickly gather news titles, publication dates, community names, rankings, and member counts for research or analysis. Ideal for marketers, researchers, and community managers seeking structured MIXI data.
Learn more ->
Kiwi Box Scraper
The Thunderbit Kiwi Box Scraper lets you extract data from Kiwi Box blogs and posts with AI-powered field suggestions. Gather blog titles, authors, publication dates, categories, and post content for research, marketing, or content analysis. Ideal for marketers, researchers, and content creators seeking structured Kiwi Box data.
Learn more ->
4PDA Scraper
The Thunderbit 4PDA Scraper lets you extract data from 4PDA news articles and forum posts using AI. Quickly gather article titles, publication dates, authors, and post content for research, analysis, or monitoring tech discussions. Ideal for tech enthusiasts, researchers, and marketers seeking structured 4PDA data.
Learn more ->
eFind Scraper
The Thunderbit eFind Scraper lets you extract data from eFind's video and news search results pages. Use AI-powered field suggestions to quickly gather video titles, URLs, durations, upload dates, news article details, and more for research, marketing, or analysis. Ideal for marketers, researchers, and content creators seeking structured eFind data.
Learn more ->
Pizza Marketplace Scraper
The Thunderbit Pizza Marketplace Scraper lets you extract data from Pizza Marketplace news listings and vendor directories. Use AI-powered field suggestions to quickly gather news titles, publication dates, authors, vendor names, locations, and contact details for research, marketing, or analysis.
Learn more ->
Investing.com scraper
Extract stock data — symbols, prices, volume, and market cap — from Investing.com in 2 clicks, then export directly to Google Sheets, Notion, or Excel. Open any Investing.com page and let AI identify the fields for you.
Learn more ->Ready to supercharge your data extraction?
Join 200,000+ professionals already using Thunderbit to automate their web scraping workflows.
Free trial provides unlimited credits for 8 webpages.



