Social Media Scraper for Cross-Platform Public Data













Collect public social data without rebuilding the workflow
Let AI handle changing layouts, process URL lists in bulk, and open linked pages when deeper fields matter.
Keep collecting when page layouts move
Thunderbit reads visible labels and content instead of relying only on fixed selectors. When a public profile or post changes shape, the workflow needs less hands-on repair.
Run profile and post URLs as a batch
Paste the public pages you want to research and process them together. Usernames, captions, dates, and visible engagement can arrive as rows ready for review or export.
Bring linked details into the same table
When a list page is only the starting point, subpage scraping can open accessible profiles or posts and append the visible details you request as new columns.
Stop rebuilding social scrapers platform by platform
Traditional tools encode each layout separately. Thunderbit keeps one AI workflow and each platform's visible labels.
A stack of platform-specific scrapers
Every source brings another setupOne agent for the public pages you choose
Thunderbit adapts the requested fields30 useful fields for public social research
Availability and metric names vary by platform. Keep the source platform and page type beside every captured value.
- Platform Name
- Source Page Type
- Source URL
- Profile ID
- Profile Username
- Profile Display Name
- Profile URL
- Profile Avatar URL
- Profile Bio
- Profile Website URL
- Profile Verification Status
- Follower Count
- Following Count
- Subscriber Count
- Post ID
- Post URL
- Post Text or Caption
- Post Published Date
- Post Type
- Media Type
- Primary Media URL
- Hashtag List
- Mentioned Accounts
- Post Like Count
- Post Comment Count
- Post Share Count
- Post View Count
- Comment ID
- Comment Text
- Comment Author Username
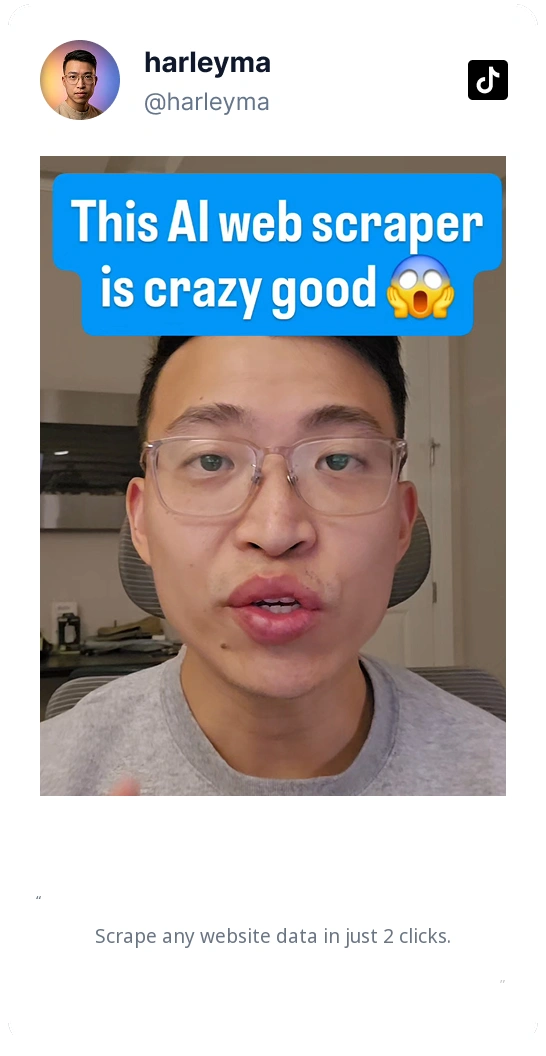
Hear how teams use one scraper across the web
Thunderbit users share how they collect public data from changing pages without maintaining a separate tool for every source.
Questions for building a defensible social-media dataset
Scope, metric meaning, public access, and schema choices across platforms.
Switch to a platform-specific scraper when precision matters
Use dedicated TikTok comments, Telegram channel, Patreon membership, YouTube, Instagram, or X pages when the task depends on platform-only entities, fields, or interaction patterns.
Minds Scraper
The Thunderbit Minds Scraper lets you extract data from Minds newsfeeds and group members with AI-powered field suggestions. Gather post titles, author names, likes, comments, and group member details for research, marketing, or community analysis. Export structured Minds data quickly and efficiently.
Learn more ->
MeWe Scraper
The Thunderbit MeWe Scraper lets you extract data from MeWe user profiles and group posts with AI-powered field suggestions. Gather profile names, bios, join dates, post content, likes, and comments for research, marketing, or analysis. Ideal for marketers, researchers, and businesses seeking structured MeWe data.
Learn more ->
Parler Scraper
The Thunderbit Parler Scraper lets you extract data from Parler search results and hashtag lists with AI-powered field suggestions. Gather search terms, user posts, hashtags, popularity scores, and more for research, marketing, or content analysis. Ideal for marketers, researchers, and businesses seeking structured Parler data.
Learn more ->
Odnoklassniki Scraper
The Thunderbit Odnoklassniki Scraper lets you extract data from Odnoklassniki groups and game lists with AI-powered field suggestions. Gather group names, descriptions, member counts, game details, ratings, and more for research, marketing, or analysis. Ideal for marketers, researchers, and businesses seeking structured Odnoklassniki data.
Learn more ->
Triller Scraper
The Thunderbit Triller Scraper lets you extract data from Triller blog pages and creator collective profiles. Use AI-powered field suggestions to quickly gather blog titles, publication dates, author names, creator bios, and follower counts for research, marketing, or analysis.
Learn more ->
Mastodon Scraper
The Thunderbit Mastodon Scraper lets you extract data from Mastodon apps and blog pages with AI-powered field suggestions. Gather app names, descriptions, platforms, blog titles, summaries, and publication dates for research, marketing, or analysis. Ideal for developers, marketers, and researchers seeking structured Mastodon data.
Learn more ->Ready to supercharge your data extraction?
Join 200,000+ professionals already using Thunderbit to automate their web scraping workflows.
Free trial provides unlimited credits for 8 webpages.



