Telegram Scraper













Collect public Telegram posts without a custom scraper
Extract the open channel view, research linked sources, and return when new messages matter.
Turn the open channel into a table
One Click Extract can recognize visible message text, usernames, timestamps, reactions, and media details on a public Telegram page without mapping the page first.
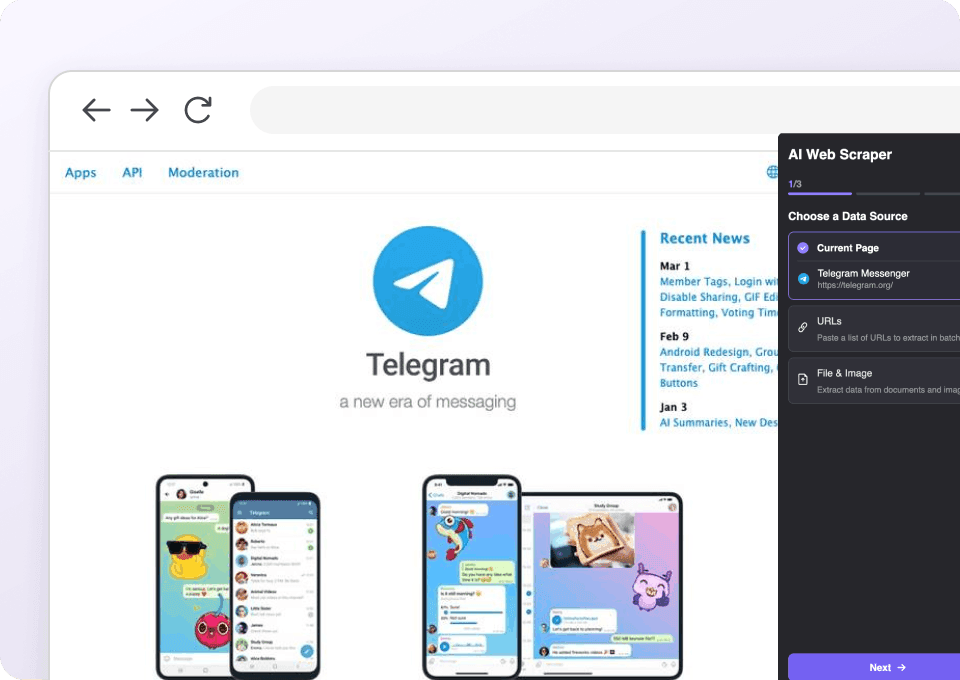
Continue from Telegram to the linked web
Use Thunderbit on public pages shared by a channel too. One workflow can cover the message archive and the outside sources you choose to research next.
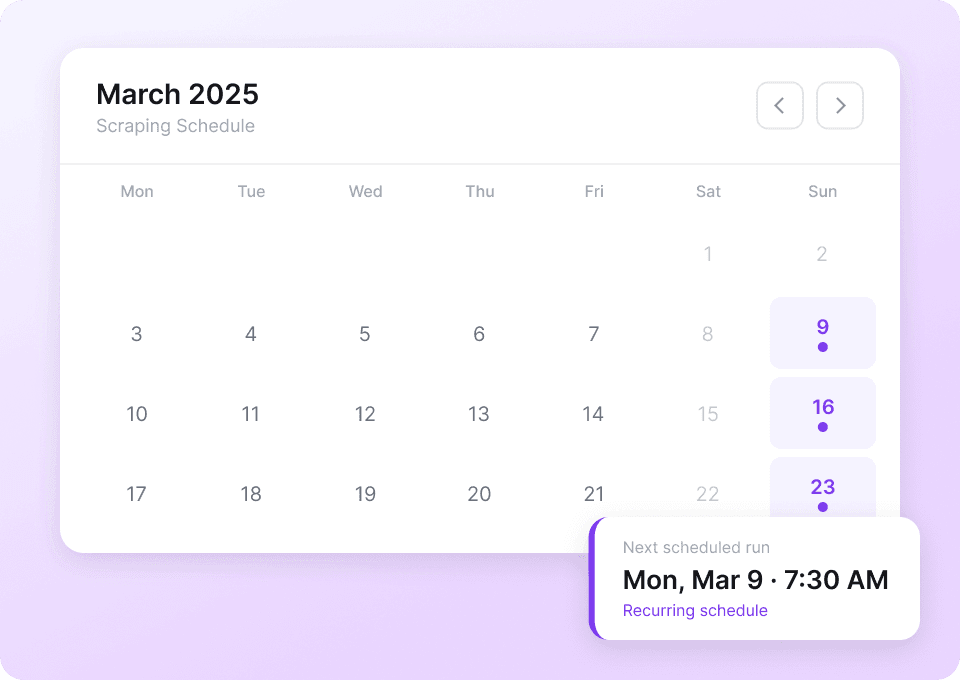
Schedule fresh channel snapshots
Set recurring runs for public channels you monitor. New visible messages, timestamps, views, or reactions can be delivered to your spreadsheet without reopening the channel each time.
Skip the upkeep behind public-channel scraping
Telegram pages keep moving as posts and media accumulate. Thunderbit handles the browser-visible structure for you.
Hand-built channel extraction
Each content type adds another ruleTelegram rows prepared by an AI agent
The open channel supplies the contextFields for public Telegram channel research
Capture browser-visible channel, message, reaction, poll, and media details. Private conversations, hidden members, and restricted files are excluded.
- Channel Title
- Channel Username
- Channel URL
- Channel Description
- Subscriber Count
- Channel Verification Status
- Discussion Group Link
- Message ID
- Message URL
- Message Date
- Message Time
- Edited Date
- Message Text
- Message Caption
- Author Signature
- Sender Display Name
- Message View Count
- Forward Count
- Reply Count
- Discussion Thread URL
- Pinned Message Status
- Reaction Emoji
- Reaction Count
- Poll Question
- Poll Options
- Poll Total Voter Count
- Media Type
- Photo URL
- Video URL
- Link Preview URL
Watch real users hand repetitive browsing to Thunderbit
Their videos show where an AI web scraper fits into day-to-day research and monitoring.
Telegram scraper questions
What a public-channel dataset can contain and where it stops.
Research the links shared in Telegram
Use a page-specific scraper for recurring news, product, or community links instead of mixing external claims into the message archive.
Minds Scraper
The Thunderbit Minds Scraper lets you extract data from Minds newsfeeds and group members with AI-powered field suggestions. Gather post titles, author names, likes, comments, and group member details for research, marketing, or community analysis. Export structured Minds data quickly and efficiently.
Learn more ->
MeWe Scraper
The Thunderbit MeWe Scraper lets you extract data from MeWe user profiles and group posts with AI-powered field suggestions. Gather profile names, bios, join dates, post content, likes, and comments for research, marketing, or analysis. Ideal for marketers, researchers, and businesses seeking structured MeWe data.
Learn more ->
Parler Scraper
The Thunderbit Parler Scraper lets you extract data from Parler search results and hashtag lists with AI-powered field suggestions. Gather search terms, user posts, hashtags, popularity scores, and more for research, marketing, or content analysis. Ideal for marketers, researchers, and businesses seeking structured Parler data.
Learn more ->
Odnoklassniki Scraper
The Thunderbit Odnoklassniki Scraper lets you extract data from Odnoklassniki groups and game lists with AI-powered field suggestions. Gather group names, descriptions, member counts, game details, ratings, and more for research, marketing, or analysis. Ideal for marketers, researchers, and businesses seeking structured Odnoklassniki data.
Learn more ->
Triller Scraper
The Thunderbit Triller Scraper lets you extract data from Triller blog pages and creator collective profiles. Use AI-powered field suggestions to quickly gather blog titles, publication dates, author names, creator bios, and follower counts for research, marketing, or analysis.
Learn more ->
Mastodon Scraper
The Thunderbit Mastodon Scraper lets you extract data from Mastodon apps and blog pages with AI-powered field suggestions. Gather app names, descriptions, platforms, blog titles, summaries, and publication dates for research, marketing, or analysis. Ideal for developers, marketers, and researchers seeking structured Mastodon data.
Learn more ->Ready to supercharge your data extraction?
Join 200,000+ professionals already using Thunderbit to automate their web scraping workflows.
Free trial provides unlimited credits for 8 webpages.



