MUJI Scraper













Extract Muji product data effortlessly
Thunderbit simplifies scraping product information from Muji's website in just two clicks.
Bulk scraping hundreds of Muji pages
Manually pulling product names, prices, descriptions, and color options from Muji one page at a time is painfully slow. Thunderbit lets you bulk-scrape hundreds of Muji product pages at once — paste in a list of URLs and it handles the rest, extracting everything at scale without any manual work.
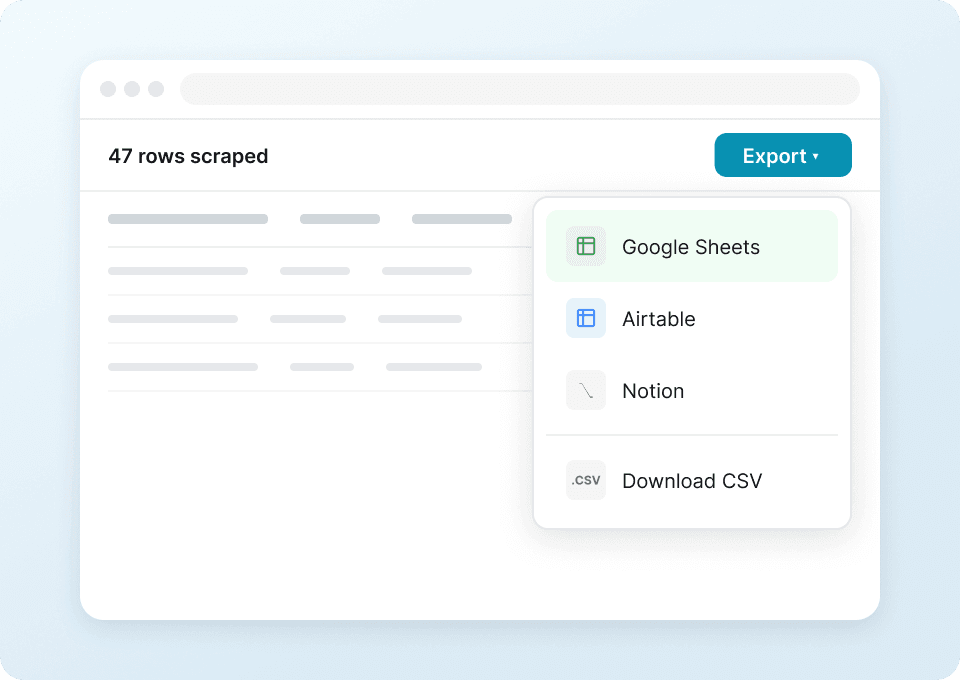
One-click export for Muji data
Stop copy-pasting Muji product details into spreadsheets. With Thunderbit, you can send your scraped data — product IDs, sizes, descriptions, and more — directly to Google Sheets, Notion, or Airtable in a single click. Your workflow stays clean; manual data entry stays out of it.
Get complete Muji product details
Muji category pages rarely show the full picture. Thunderbit automatically follows each product link to its detail page, pulling everything from material descriptions to available sizes and color options. You get a complete, structured record for every Muji product — no manual clicking required.
Why is Thunderbit different from traditional Muji scrapers?
Stop fighting with selectors, start extracting data effortlessly from Muji.
Traditional scrapers
The old way of doing thingsThunderbit AI
The smarter approach
Frequently asked questions
Related use cases
Explore more use cases of Thunderbit's web scraper.
Sur la table Scraper
The Thunderbit Sur La Table Scraper lets you extract data from Sur La Table’s products, search results, cooking classes, and store locations. Use AI-powered field suggestions to quickly gather product details, class schedules, and store information for analysis or business insights.
Learn more ->
Superdelivery Scraper
The Thunderbit Superdelivery Scraper enables you to extract product data from Superdelivery vendor SKU lists and category pages. Use AI-powered field suggestions to quickly gather product names, prices, images, brands, and vendor details for inventory management, price comparison, or market research.
Learn more ->
Sharaf DG Scraper
The Thunderbit Sharaf DG Scraper enables you to extract structured data from Sharaf DG's product listings and SKU pages. Use AI-powered field suggestions to quickly gather product names, prices, descriptions, images, ratings, and specifications for analysis or research. Ideal for e-commerce professionals, marketers, and researchers seeking detailed Sharaf DG data.
Learn more ->
ÇiçekSepeti Scraper
The Thunderbit ÇiçekSepeti Scraper lets you extract product data from ÇiçekSepeti, including listings and SKU details. Use AI-powered field suggestions to quickly gather product names, prices, images, discounts, and codes for analysis or inventory management. Ideal for e-commerce professionals, marketers, and researchers.
Learn more ->
Vatan Bilgisayar Scraper
The Thunderbit Vatan Bilgisayar Scraper lets you extract data from Vatan Bilgisayar's product listings and SKU pages. Use AI-powered field suggestions to quickly gather product names, prices, discounts, images, and product codes for analysis or research. Ideal for e-commerce professionals, marketers, and researchers seeking structured Vatan Bilgisayar data.
Learn more ->
PTTAVM Scraper
The Thunderbit PTTAVM Scraper enables you to extract structured data from PTTAVM product listings and SKU pages. Gather product names, prices, discounts, images, and detailed descriptions quickly using AI-powered field suggestions. Ideal for e-commerce professionals, marketers, and researchers seeking accurate PTTAVM data.
Learn more ->Ready to supercharge your data extraction?
Join 200,000+ professionals already using Thunderbit to automate their web scraping workflows.
Free trial provides unlimited credits for 8 webpages.



