Flickr Scraper













Extract Flickr data in two clicks
Thunderbit simplifies data extraction from Flickr, no coding needed.
Two clicks to Flickr data
Manually copying photo titles, author usernames, or upload dates from Flickr is tedious. Thunderbit lets you skip the copy-pasting. Just point at the data you want — like the photo description or license type — and the AI figures out the rest. Two clicks, and you're extracting data without writing a single line of code.
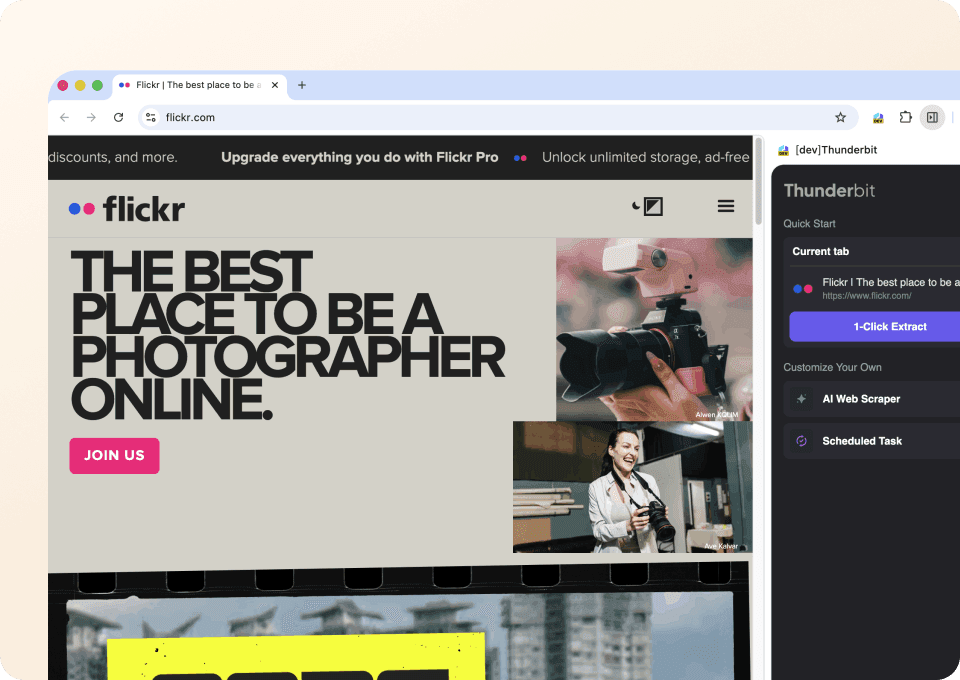
Get full Flickr photo details
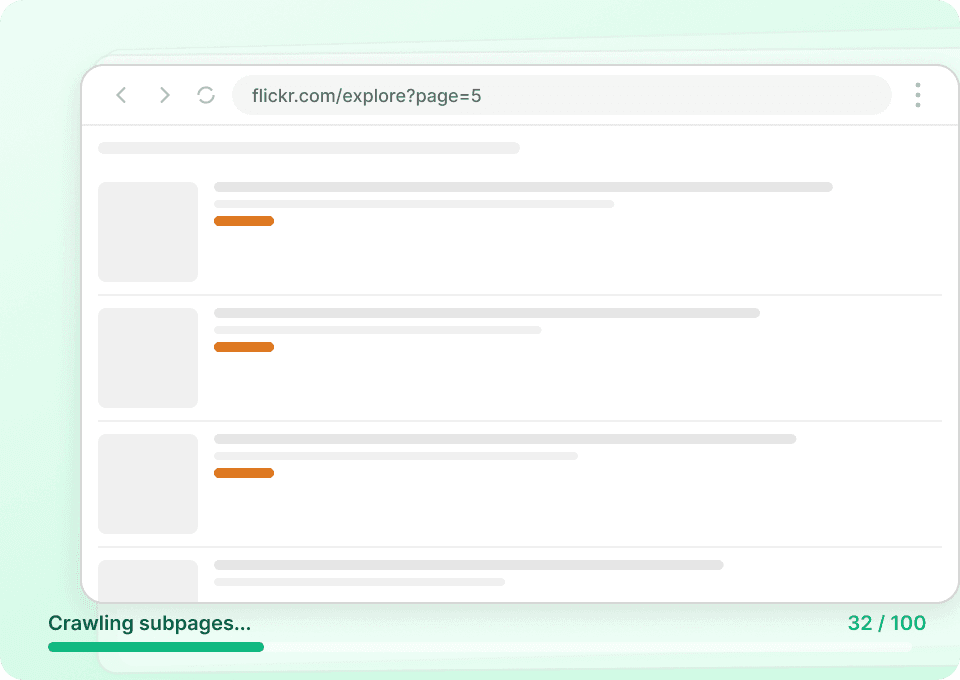
Flickr search and gallery pages only show basic info. To get the full picture, you need details from each individual photo page. Thunderbit automatically visits each linked subpage, pulls the description, tags, and other details, and appends them as new columns in your export. No more clicking through each photo page manually.
Bulk Flickr data extraction
Scraping Flickr one photo at a time is slow and impractical. Instead of manually navigating individual pages, Thunderbit lets you input multiple Flickr URLs at once. It visits each page, extracts the photo title, author username, and other data points, and consolidates everything into a single, clean dataset.
Why is Thunderbit different from traditional Flickr scrapers?
Extract data from flickr without the headache of traditional scraping.
Traditional scrapers
The old way of doing thingsThunderbit AI
The smarter approach
Frequently asked questions
Related use cases
Explore more use cases of Thunderbit's web scraper.
Minds Scraper
The Thunderbit Minds Scraper lets you extract data from Minds newsfeeds and group members with AI-powered field suggestions. Gather post titles, author names, likes, comments, and group member details for research, marketing, or community analysis. Export structured Minds data quickly and efficiently.
Learn more ->
MeWe Scraper
The Thunderbit MeWe Scraper lets you extract data from MeWe user profiles and group posts with AI-powered field suggestions. Gather profile names, bios, join dates, post content, likes, and comments for research, marketing, or analysis. Ideal for marketers, researchers, and businesses seeking structured MeWe data.
Learn more ->
Parler Scraper
The Thunderbit Parler Scraper lets you extract data from Parler search results and hashtag lists with AI-powered field suggestions. Gather search terms, user posts, hashtags, popularity scores, and more for research, marketing, or content analysis. Ideal for marketers, researchers, and businesses seeking structured Parler data.
Learn more ->
Odnoklassniki Scraper
The Thunderbit Odnoklassniki Scraper lets you extract data from Odnoklassniki groups and game lists with AI-powered field suggestions. Gather group names, descriptions, member counts, game details, ratings, and more for research, marketing, or analysis. Ideal for marketers, researchers, and businesses seeking structured Odnoklassniki data.
Learn more ->
Triller Scraper
The Thunderbit Triller Scraper lets you extract data from Triller blog pages and creator collective profiles. Use AI-powered field suggestions to quickly gather blog titles, publication dates, author names, creator bios, and follower counts for research, marketing, or analysis.
Learn more ->
Mastodon Scraper
The Thunderbit Mastodon Scraper lets you extract data from Mastodon apps and blog pages with AI-powered field suggestions. Gather app names, descriptions, platforms, blog titles, summaries, and publication dates for research, marketing, or analysis. Ideal for developers, marketers, and researchers seeking structured Mastodon data.
Learn more ->Ready to supercharge your data extraction?
Join 200,000+ professionals already using Thunderbit to automate their web scraping workflows.
Free trial provides unlimited credits for 8 webpages.



