Baidu Scraper for Search Results and Articles













Turn Baidu results into clean, useful data
Keep search results and available article details in one clear table.
Clean Baidu data as you collect it
Thunderbit places visible titles, URLs, snippets, dates, and sources in clear columns. If a result does not show a field, the cell stays blank.

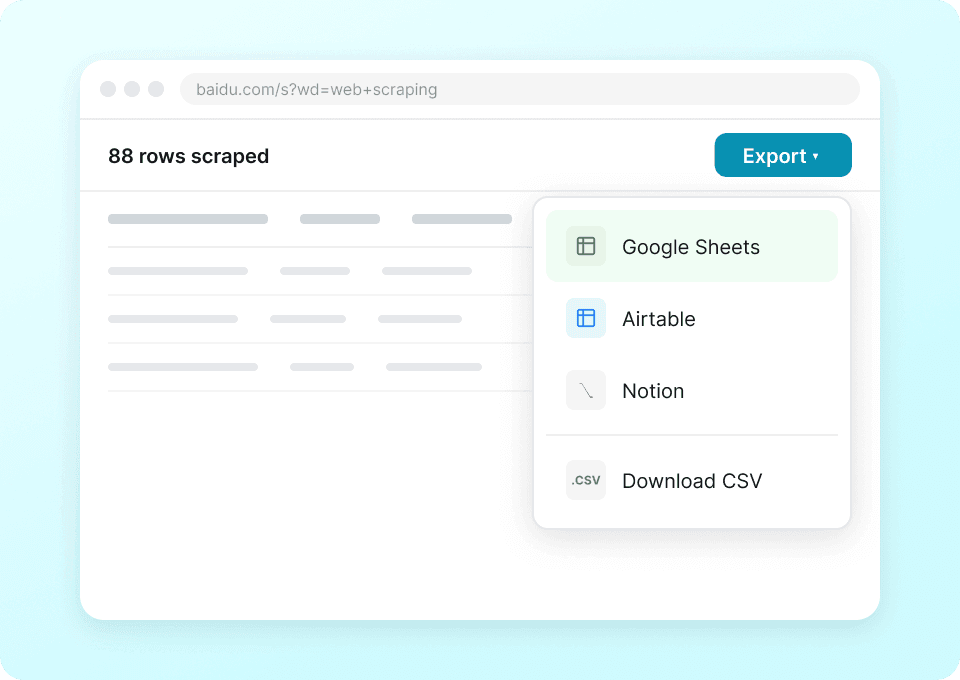
Export Baidu research in one click
Send each run to a search-results review sheet. Ranks, sources, dates, and linked-page details stay beside the matching Baidu result.
Use the same workflow on any site
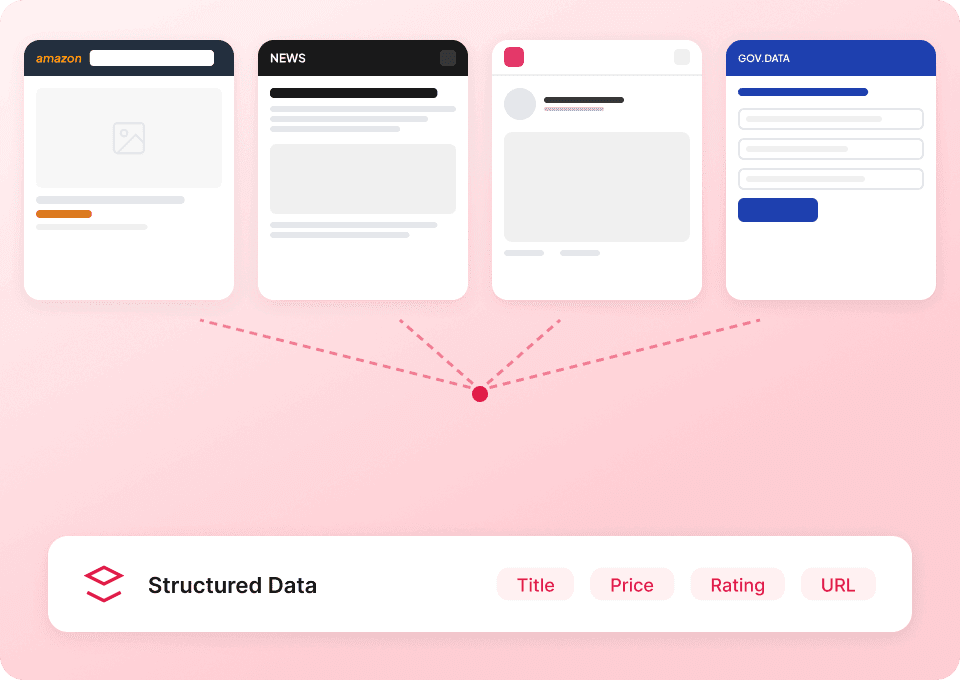
Thunderbit reads fields by meaning, not one Baidu layout. Use the same approach on any accessible public site when your research reaches a new source.
Keep the context around every Baidu result
A link list loses context. Thunderbit keeps visible details beside each result.
Copied links and loose notes
Result details become separatedStructured Baidu research
Visible context stays with each resultWhat data can you extract from Baidu?
Choose from these public, visible fields. Result modules and linked pages do not show every field for every query.
- Search Query
- Result Rank
- Result Title
- Result URL
- Displayed URL
- Result Snippet
- Result Date
- Result Site Icon
- Related Search Phrase
- Spelling Suggestion
- Pinyin Suggestion
- Search Result Page Number
- Source Site
- Source Domain
- Article Author
- Article Publication Date
- Article Abstract
- Document Name
- Document Description
- Document Breadcrumb
- Document Genre
- Document File Format
- Document Page Count
- Document Upload Time
- Document URL
- Result Content Type
- Image Thumbnail
- Video Thumbnail
- Location Address
- Baidu Feature Module
See how researchers track Chinese search results
These user feedback videos show how people review Chinese search results, track sources, and check linked articles.
Questions about collecting Baidu search data
Available fields vary by query, result type, and the information shown on linked pages.
Continue from Baidu results to source-page research
Explore article and website scrapers when you need full page text or other details beyond the fields shown in Baidu results.
Statarea Scraper
The Thunderbit Statarea Scraper lets you extract football match predictions, team details, comparisons, and TV schedules from Statarea. Use AI-powered field suggestions to quickly gather structured data for sports analysis, betting, or content creation. Ideal for analysts, fans, and content creators seeking organized football data.
Learn more ->
Fooby Scraper
The Thunderbit Fooby Scraper lets you extract recipe data from Fooby, including recipe names, ingredients, preparation times, and nutritional values. Use AI-powered field suggestions to quickly gather structured recipe information for food blogs, nutrition analysis, or culinary projects.
Learn more ->
Swissmilk Scraper
The Swissmilk Scraper by Thunderbit lets you extract structured recipe data from Swissmilk's listing and individual recipe pages. Gather recipe names, ingredients, preparation steps, images, and more for culinary research, blogging, or menu planning. Ideal for food bloggers, chefs, and marketers seeking organized recipe data.
Learn more ->
Gutekueche Scraper
The Thunderbit Gutekueche Scraper lets you extract structured data from Gutekueche recipe listings and product pages. Use AI-powered field suggestions to quickly gather recipe names, descriptions, prices, images, ratings, and reviews for content creation, research, or analysis. Ideal for food bloggers, marketers, and researchers seeking organized Gutekueche data.
Learn more ->
Chefkoch Scraper
The Thunderbit Chefkoch Scraper lets you extract structured data from Chefkoch recipe listings and product pages. Use AI-powered field suggestions to quickly gather recipe names, descriptions, images, ratings, and reviews for analysis, content creation, or research.
Learn more ->
Talabat Scraper
The Thunderbit Talabat Scraper enables you to extract data from Talabat restaurant listings and individual restaurant pages. Use AI-powered field suggestions to quickly gather restaurant names, cuisine types, images, best seller dishes, ratings, and reviews for analysis or research. Ideal for marketers, researchers, and business owners seeking structured Talabat data.
Learn more ->Ready to supercharge your data extraction?
Join 200,000+ professionals already using Thunderbit to automate their web scraping workflows.
Free trial provides unlimited credits for 8 webpages.



