News Scraper: Connect Headlines to Full Article Details













Connect News Headlines to Full Articles
Turn a headline watchlist into article records with source context.
Open Articles for Full Details
Start from a topic, section, or results page. Thunderbit can visit each linked story and add the byline, published time, section, summary, and article URL shown there.
Process a List of Article URLs
Paste the links selected by an editor or researcher. Each accessible story becomes its own row, keeping the source and publication details tied to the right headline.
Refresh a News Watchlist
Schedule the same source pages for a later run. The new table shows the stories and headline details visible at that time.
Build a News Watchlist Without Building a Scraper
Move from headlines to author, date, section, and source detail in one table.
Manual Lists or Selector Tools
More setup for every sourceThunderbit AI Agent
Open a news page and startArticle and listing fields in scope
Captured only when visible in your session.
- headline
- article_url
- outlet_name
- author_name
- author_profile_url
- byline
- publication_date
- publication_time
- updated_date
- updated_time
- section
- subsection
- tags
- summary
- lead_paragraph
- body_text_snippet
- dateline_location
- estimated_read_time
- image_url
- image_caption
- image_credit
- video_url
- video_title
- video_duration
- gallery_image_count
- comment_count
- share_count
- related_titles
- related_urls
- publisher_logo_url
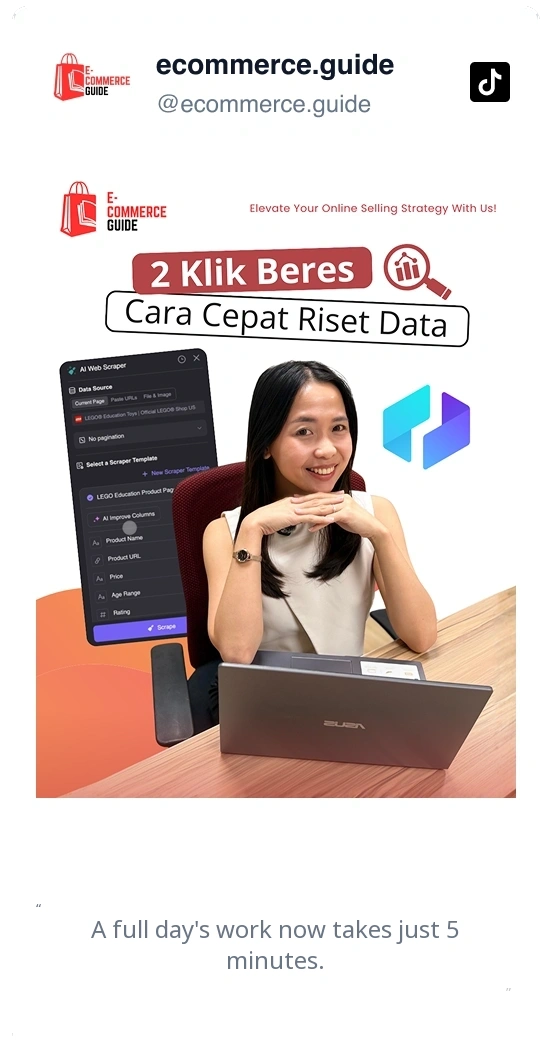
Watch news researchers build a usable watchlist
In user videos, news teams show how they match headlines with article details and check each row.
Questions about moving from headlines to context
Short answers for news listings and articles.
Continue from headlines to source research
Collect author pages, press releases, publication archives, or topic feeds that support the same news question.
MIXI Scraper
The Thunderbit MIXI Scraper lets you extract data from MIXI news listings and community ranking pages. Use AI-powered field suggestions to quickly gather news titles, publication dates, community names, rankings, and member counts for research or analysis. Ideal for marketers, researchers, and community managers seeking structured MIXI data.
Learn more ->
Kiwi Box Scraper
The Thunderbit Kiwi Box Scraper lets you extract data from Kiwi Box blogs and posts with AI-powered field suggestions. Gather blog titles, authors, publication dates, categories, and post content for research, marketing, or content analysis. Ideal for marketers, researchers, and content creators seeking structured Kiwi Box data.
Learn more ->
4PDA Scraper
The Thunderbit 4PDA Scraper lets you extract data from 4PDA news articles and forum posts using AI. Quickly gather article titles, publication dates, authors, and post content for research, analysis, or monitoring tech discussions. Ideal for tech enthusiasts, researchers, and marketers seeking structured 4PDA data.
Learn more ->
eFind Scraper
The Thunderbit eFind Scraper lets you extract data from eFind's video and news search results pages. Use AI-powered field suggestions to quickly gather video titles, URLs, durations, upload dates, news article details, and more for research, marketing, or analysis. Ideal for marketers, researchers, and content creators seeking structured eFind data.
Learn more ->
Pizza Marketplace Scraper
The Thunderbit Pizza Marketplace Scraper lets you extract data from Pizza Marketplace news listings and vendor directories. Use AI-powered field suggestions to quickly gather news titles, publication dates, authors, vendor names, locations, and contact details for research, marketing, or analysis.
Learn more ->
Investing.com scraper
Extract stock data — symbols, prices, volume, and market cap — from Investing.com in 2 clicks, then export directly to Google Sheets, Notion, or Excel. Open any Investing.com page and let AI identify the fields for you.
Learn more ->Ready to supercharge your data extraction?
Join 200,000+ professionals already using Thunderbit to automate their web scraping workflows.
Free trial provides unlimited credits for 8 webpages.


