Goodreads scraper













Extract Goodreads data in seconds, not hours
Two clicks to scrape Goodreads data
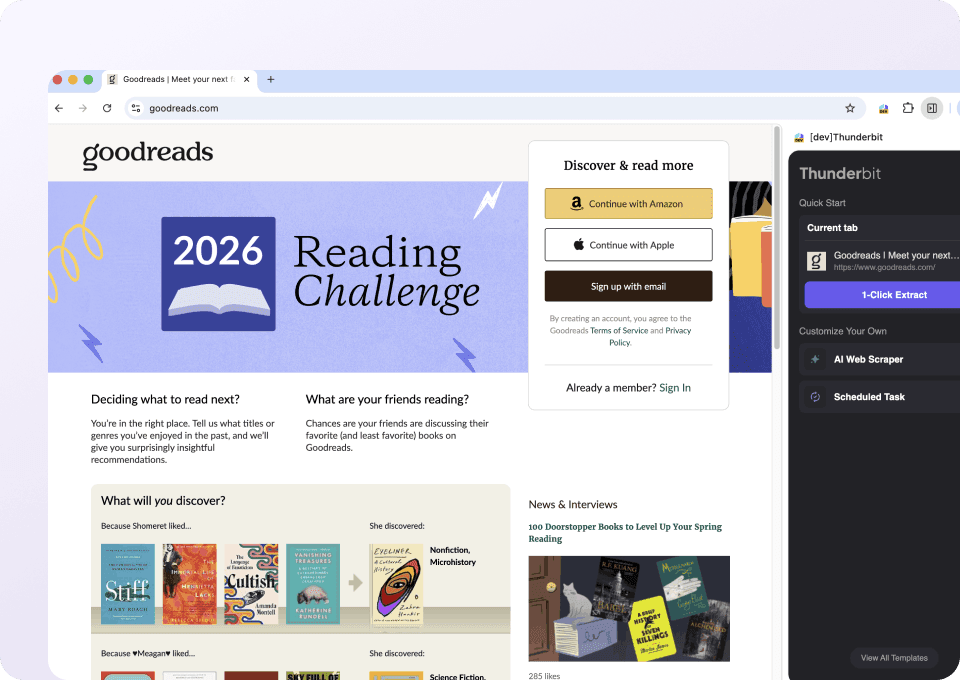
Tired of manually copying book titles, author names, ratings, and page counts from Goodreads? Thunderbit lets you extract the data you need in just two clicks — no coding or setup required. Simply point at the fields you want, and the AI detects and captures them automatically.
Clean Goodreads data, ready to use
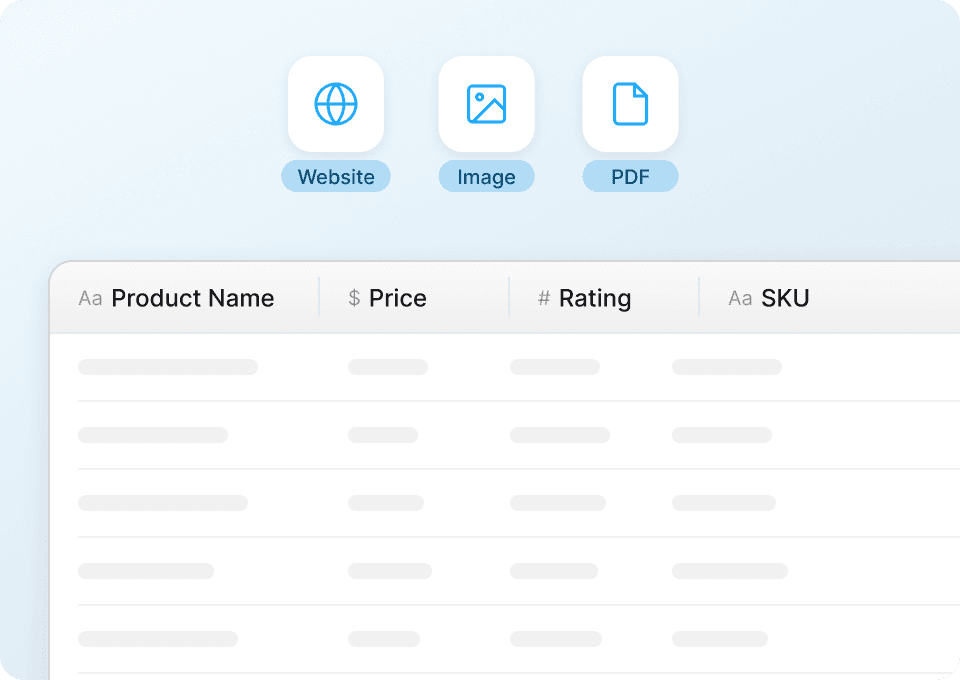
Goodreads data can be messy and inconsistent. Thunderbit automatically cleans and structures the data as it extracts it — so you get a perfectly formatted spreadsheet with book titles, authors, average ratings, review counts, and page numbers, all ready for analysis. No manual cleanup required.
Scrape hundreds of Goodreads pages
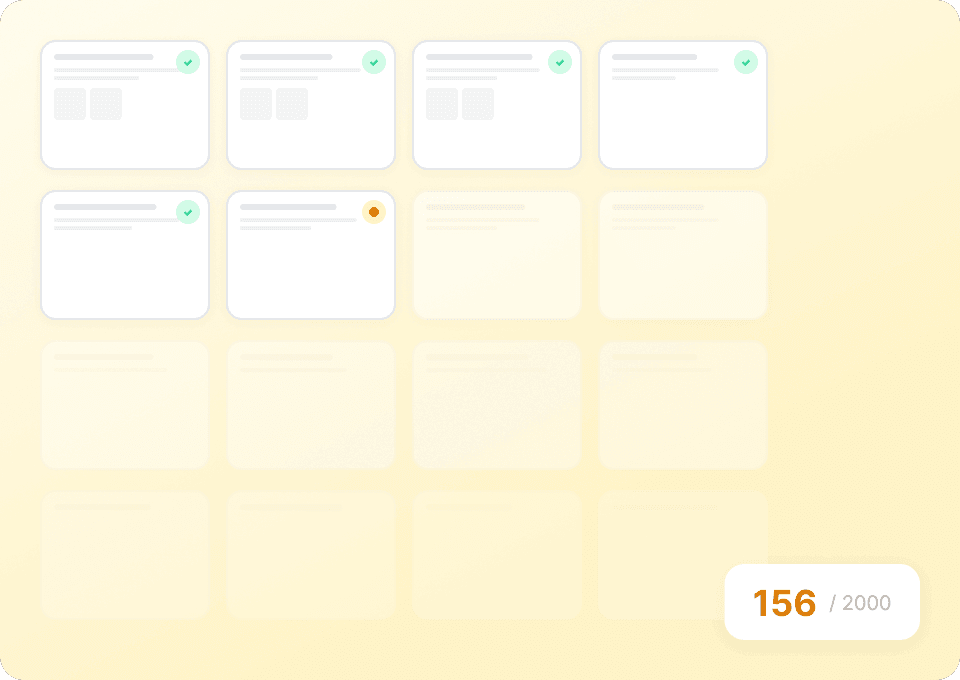
Manually visiting Goodreads one page at a time is slow and error-prone. Thunderbit handles bulk scraping automatically — just supply a list of URLs and it extracts book titles, authors, ratings, and more across hundreds of pages at once, quickly and without interruption.
Goodreads scraping got you down?
See how Thunderbit simplifies data extraction from Goodreads.
Traditional scrapers
The old way of doing thingsThunderbit
The smarter approach
Frequently asked questions
Related use cases
Explore more use cases of Thunderbit's web scraper.
Statarea Scraper
The Thunderbit Statarea Scraper lets you extract football match predictions, team details, comparisons, and TV schedules from Statarea. Use AI-powered field suggestions to quickly gather structured data for sports analysis, betting, or content creation. Ideal for analysts, fans, and content creators seeking organized football data.
Learn more ->
Fooby Scraper
The Thunderbit Fooby Scraper lets you extract recipe data from Fooby, including recipe names, ingredients, preparation times, and nutritional values. Use AI-powered field suggestions to quickly gather structured recipe information for food blogs, nutrition analysis, or culinary projects.
Learn more ->
Swissmilk Scraper
The Swissmilk Scraper by Thunderbit lets you extract structured recipe data from Swissmilk's listing and individual recipe pages. Gather recipe names, ingredients, preparation steps, images, and more for culinary research, blogging, or menu planning. Ideal for food bloggers, chefs, and marketers seeking organized recipe data.
Learn more ->
Gutekueche Scraper
The Thunderbit Gutekueche Scraper lets you extract structured data from Gutekueche recipe listings and product pages. Use AI-powered field suggestions to quickly gather recipe names, descriptions, prices, images, ratings, and reviews for content creation, research, or analysis. Ideal for food bloggers, marketers, and researchers seeking organized Gutekueche data.
Learn more ->
Chefkoch Scraper
The Thunderbit Chefkoch Scraper lets you extract structured data from Chefkoch recipe listings and product pages. Use AI-powered field suggestions to quickly gather recipe names, descriptions, images, ratings, and reviews for analysis, content creation, or research.
Learn more ->
Talabat Scraper
The Thunderbit Talabat Scraper enables you to extract data from Talabat restaurant listings and individual restaurant pages. Use AI-powered field suggestions to quickly gather restaurant names, cuisine types, images, best seller dishes, ratings, and reviews for analysis or research. Ideal for marketers, researchers, and business owners seeking structured Talabat data.
Learn more ->Ready to supercharge your data extraction?
Join 200,000+ professionals already using Thunderbit to automate their web scraping workflows.
Free trial provides unlimited credits for 8 webpages.



