
Indeed sits on a mountain of job data — 645M+ job seeker profiles, 3.3M+ employers, and 24M+ active job listings at any given time.
If you want that data in a spreadsheet, a CRM, or an analytics dashboard, you need a scraper that actually works. "Actually works" is the operative phrase, because Indeed is one of the most aggressively protected job boards on the public web.
I've spent years building automation tools at Thunderbit and before that at Automation Anywhere, and I can tell you: scraping Indeed in 2026 is not the same as scraping a basic product catalog. Cloudflare challenges, CAPTCHAs, IP fingerprinting, and rolling rate limits mean that half the scripts people wrote last year are already broken. Forum after forum tells the same story — code that ran for months suddenly returns nothing but 403 errors.
So I put together this list of 10 Indeed scrapers that span no-code extensions, developer APIs, and open-source libraries, covering every skill level and budget. Whether you're a recruiter who just wants salary data in Google Sheets or a data engineer building a job aggregation pipeline, there's a tool here for you.
Why Indeed Is One of the Hardest Job Boards to Scrape
Before we get into the tools, it helps to understand what you're up against. Indeed is not a friendly target for scrapers, and it has gotten less friendly every year.
Four layers of anti-bot defense make it stand out:
- Cloudflare WAF: Indeed's own support documentation acknowledges that users may encounter Cloudflare errors and 403 Forbidden responses. This is the first wall most scrapers hit.
- CAPTCHA and challenge gates: Repeated "Verify that you are human" loops are common. These aren't just annoying — they break automated workflows entirely unless your tool can solve or bypass them.
- IP and request rate limiting: Indeed's developer docs enforce traffic on a rolling 60-second window and return HTTP 429 when exceeded. Pagination is where this bites hardest.
- JavaScript and cookie dependency: Indeed explicitly tells blocked users to enable JavaScript and cookies. Pure HTTP request scrapers — the kind that don't render a real browser — fail consistently.
The community evidence is blunt. One Reddit user wrote, "I am always getting a 403 forbidden error." Another reported that "the webscraping code I've been running for months has stopped working." A later thread described the first page loading fine but subsequent pages failing completely.
Compared to other job boards, Indeed sits in the middle-to-hard range. Scraperly's site guides rate it as roughly medium difficulty with safe throughput around 200–500 listings per day per IP, while Glassdoor and LinkedIn tend to be even harder due to login gates. But "medium difficulty" still means cheap request-only scrapers and hobby scripts break often. The tool you pick matters more here than on most sites.
How We Picked the Best Indeed Scrapers for 2026
I evaluated every tool in this list against eight criteria, each tied directly to real user pain points I found across Reddit, GitHub issues, and developer forums:
| Criterion | Why It Matters on Indeed |
|---|---|
| Cloudflare / Anti-Bot Bypass | The #1 complaint — five separate forum threads mention 403 blocks breaking scrapers |
| Coding Required | Non-coders (recruiters, HR, analysts) are a huge audience but get ignored by most scraper lists |
| Free Tier / Free Option | Four forum mentions of needing free or low-cost options; paid tools called "too expensive" |
| Export Formats | Users need data in Sheets, Excel, Airtable — not raw JSON they have to transform manually |
| Proxy / IP Rotation | Three mentions; scraping Indeed without proxies is, as one user put it, "a bad idea" |
| Ease of Setup | Users report Python scrapers "making my head spin" |
| Maintenance / Reliability | Indeed changes fast enough to punish unmaintained tools |
| Cost per 1K Jobs Scraped | Competitor articles give vague pricing; I normalized costs for apples-to-apples comparison |
One thing that makes this list different from most: I deliberately included no-code, low-code, API, and open-source tools. Every other "best Indeed scraper" article I found only covers API-based options.
That leaves out a huge chunk of people who just want job data in a spreadsheet without touching a terminal.
Which Indeed Scraper Fits Your Skill Level?
Before you read through all ten tools, figure out which category you fall into. It'll save you time.
| Your Skill Level | Best-Fit Approach | Tools to Consider |
|---|---|---|
| No coding experience | Chrome extension or config UI | Thunderbit, Apify (config UI) |
| Basic Python / scripting | Library + proxies or simple API | JobSpy, ScraperAPI, Decodo |
| Developer / data engineer | Full API integration | Bright Data, Oxylabs, ZenRows, ScrapingBee, Scrapingdog |
A recruiter who wants salary data for 50 job postings doesn't need a $500/month enterprise proxy network. And someone building a commercial job aggregator probably shouldn't rely on a free Chrome extension. Matching the tool to your skill level and use case is half the battle.
1. Thunderbit — Best Indeed Scraper for Non-Technical Users
 Thunderbit is the tool my team and I built, so I'll be upfront about that. But the reason it's first on this list isn't bias — it's that Thunderbit is the only true no-code Indeed scraper I've found that handles anti-bot protection, subpage enrichment, and direct spreadsheet exports without requiring a single line of code.
The workflow is simple. Install the Chrome Extension, navigate to an Indeed search results page, click AI Suggest Fields (the AI reads the page and proposes columns like Job Title, Company, Salary, Location, URL), review the suggested fields, click Scrape, and export. The whole process takes about 2 minutes from install to data in your spreadsheet.
What makes Thunderbit particularly useful on Indeed:
- Subpage scraping: Start from a search results page, then automatically visit each job detail page to append full descriptions, requirements, benefits, and posting metadata. For competitive hiring analysis, this is the feature that matters most — you get the full picture, not just the listing snippet.
- Browser + Cloud scraping modes: Browser mode scrapes from your own logged-in Chrome session (useful for location-specific results). Cloud mode uses Thunderbit's hosted infrastructure with rotating IPs and anti-blocking logic — it can scrape up to 50 pages at once for public targets.
- Built-in anti-bot handling: Cloud mode handles Cloudflare challenges and CAPTCHAs automatically. No proxy setup, no CAPTCHA-solving service to configure.
- Free email/phone extractors: Pull employer contact data directly from company pages — useful for recruiter lead generation.
- Direct exports: Google Sheets, Excel/CSV, Airtable, and Notion — all free. No JSON-to-CSV conversion scripts needed.
The Indeed scraper template is pre-built, so you don't even need to configure fields manually if you don't want to.
Try Thunderbit for Indeed scraping
Pricing: Thunderbit's free plan includes 6 pages per month, and the free trial gives you 10 pages. Paid plans are credit-based (1 credit = 1 output row), working out to roughly $30 per 1,000 rows on Starter pricing, with lower rates on higher tiers. All exports are completely free regardless of plan. Full pricing details here.
Pros: Zero coding, direct spreadsheet exports, subpage enrichment, browser + cloud modes, very fast setup
Cons: Credit-based billing is less attractive for very high-volume crawls (10,000+ listings/day); independent Indeed-specific success rate benchmarks are limited
Best for: Recruiters, HR teams, and business analysts who need Indeed data in a spreadsheet — no code required.
2. Bright Data — Best Indeed Scraper for Enterprise-Scale Projects
 Bright Data is the heavyweight in this category. It combines a massive proxy network (400M+ monthly IPs across 195 countries), dedicated CAPTCHA solving, browser fingerprinting, JavaScript rendering, and purpose-built Indeed job posting datasets and a Jobs Data API.
- Key features: Web Unlocker for Cloudflare bypass, geo-targeted scraping, structured dataset delivery (JSON, CSV, NDJSON), cloud storage integration, and dedicated Indeed data products
- Anti-bot handling: Best-in-class. Bright Data's ScrapingTest benchmark results show a directional 95.99% overall success rate at 7.45s average response time
- Pricing: Pay-as-you-go starts around $1.50 per 1,000 records for web scraping, with the Indeed dataset starting at $0.0025 per record ($250 minimum order). Free tier: 5,000 credits/month, no credit card required.
Best for: Data teams scraping thousands of Indeed pages daily for salary benchmarking, labor market research, or commercial job aggregation — especially when uptime and geographic coverage matter more than cost.
3. Apify Indeed Scraper — Best Indeed Scraper for Low-Code Users
 Apify sits in the middle of the market. It's not as beginner-friendly as Thunderbit, but it's easier than raw APIs because you can run pre-built "Actors" from a config UI. The most popular Indeed actor (misceres/indeed-scraper) shows about 4.0/5 from 54 reviews and 20K total users, with pricing from approximately $3.00 per 1,000 job listings.
- Key features: Config-based UI (set search keywords, locations, number of pages), built-in scheduling, dataset storage, and flexible exports (JSON, CSV, Excel, XML, HTML, RSS, JSONL)
- Anti-bot handling: Depends on the specific actor and proxy setup. Public issue threads show Indeed runs can still get blocked or return incomplete results.
- Pricing: Free tier includes $5 in platform credits. Actor usage can consume that quickly on Indeed.
Best for: Mid-technical users who want scheduling and structured exports through a dashboard — no scraping code from scratch.
4. ScraperAPI — Best Indeed Scraper API for Developers on a Budget
 ScraperAPI is one of the most straightforward developer APIs: send a URL, let the service handle proxy rotation, CAPTCHA solving, and JS rendering, and get back HTML or structured output. Its Indeed-specific page advertises 99.99% success and 1–3s average response times, though those are vendor-reported claims.
- Key features: Simple REST API, built-in proxy rotation, auto-retry, multiple output formats (HTML, JSON, text, markdown, CSV workflows)
- Pricing: Hobby plan is $49 for 100K credits, but protected requests can consume 10–25 credits each. Effective cost for Indeed-style protected traffic: roughly $4.90 per 1,000 protected requests on entry pricing. Free tier: 5K trial credits.
- Gotcha: If half your requests fail (which can happen on Indeed), your effective cost doubles.
Best for: Developers who value clean API docs and predictable integration without enterprise pricing.
5. Scrapingdog — Best Low-Cost API for Indeed Scraping
 Scrapingdog competes on price clarity. Plans start at $40 for 200K credits (about $0.20 per 1,000 credits), and the company offers 200 free credits to start.
- Key features: Stealth mode for anti-bot sites, parsed JSON output for Indeed, retry logic (up to 60 seconds per request), charges only for successful requests
- Pricing catch: Stealth mode costs 10 credits per request, so the real protected-site cost on Lite pricing is closer to $2.00 per 1,000 protected requests. Still cheap relative to most competitors.
- Performance note: ScrapingTest benchmarks show more uneven performance than Bright Data or ScraperAPI, so validate thoroughly before scaling.
A dedicated Indeed guide walks through the setup in Python.
Best for: Budget-conscious developers chasing the lowest per-request cost who don't mind validating reliability on their own queries.
6. ZenRows — Best Indeed Scraper API for Anti-Bot Reliability
 ZenRows has become one of the clearest anti-bot-first offerings in the scraping market. It explicitly markets WAF bypass, CAPTCHA bypass, fingerprinting bypass, and premium rotating proxies. Its Indeed scraper page offers exports as CSV, single JSON file, or one JSON file per URL — more business-friendly than many raw API products.
- Key features: Protected-site scraping with JS rendering, anti-bot bypass built into every request, structured output options
- Pricing: Launch plan works out to about $0.276 per 1,000 basic results, but protected results jump to roughly $6.90 per 1,000. Free plan: 5,000 credits/month, no credit card required, permanent.
- Vendor claim: 99.93% protected-site success rate average.
That per-request cost sounds steep until you compare it against the hours you'd spend debugging Cloudflare manually.
Best for: Developers whose top priority is anti-bot resilience — without stepping up to Bright Data's full enterprise stack.
7. ScrapingBee — Best Indeed Scraper API with Stealth Proxy Mode
 ScrapingBee is strongest when developer workflow matters as much as the unblocker. It supports headless browsers, rotating proxies, dedicated Cloudflare tooling, extract rules (CSS/XPath selectors and AI-assisted extraction), and multiple response formats: JSON, HTML, Markdown, CSV, and NDJSON.
- Key features: Stealth proxy mode, JS rendering, structured data extraction rules, AI-assisted parsing
- Pricing: Freelance plan is $49 for 250K credits ($0.196 per 1,000 credits), but JS + premium proxy requests cost 25 credits each, translating to roughly $4.90 per 1,000 at entry pricing. Free tier: 1,000 calls.
- Benchmark signal: ScrapingTest directional results show 77.98% overall success at 10.32s average.
Best for: Developers who care about a polished API experience and want built-in extraction rules to cut down on post-processing.
8. Oxylabs — Best Indeed Scraper for Large-Scale Proxy Infrastructure
 Oxylabs belongs on this list for teams that already know they need serious proxy and unblocker infrastructure. Its Web Scraper API and Web Unblocker support CAPTCHA bypass, JS rendering, fingerprinting mitigation, retries, and broad geotargeting across a 177M+ proxy pool in 195 countries.
- Key features: AI-powered data parsing, multi-format output (JSON, HTML, PNG, Markdown), cloud delivery options
- Pricing: Generic targets start around $1.15 per 1,000 without JS and $1.35 per 1,000 with JS on Web Scraper API entry pricing. Web Unblocker is traffic-priced. Free tier: up to 2,000 results.
- Nuance: Oxylabs doesn't package a neatly branded "Indeed scraper" the way some competitors do. You'll need to understand the product split between Web Scraper API (parsed data) and Web Unblocker (raw access).
- Benchmark signal: ScrapingTest directional results show 83.89% overall success at 12.75s average.
Best for: Enterprise teams already invested in proxy infrastructure, or anyone who needs geographic targeting at serious scale.
9. JobSpy (python-jobspy) — Best Free Open-Source Indeed Scraper
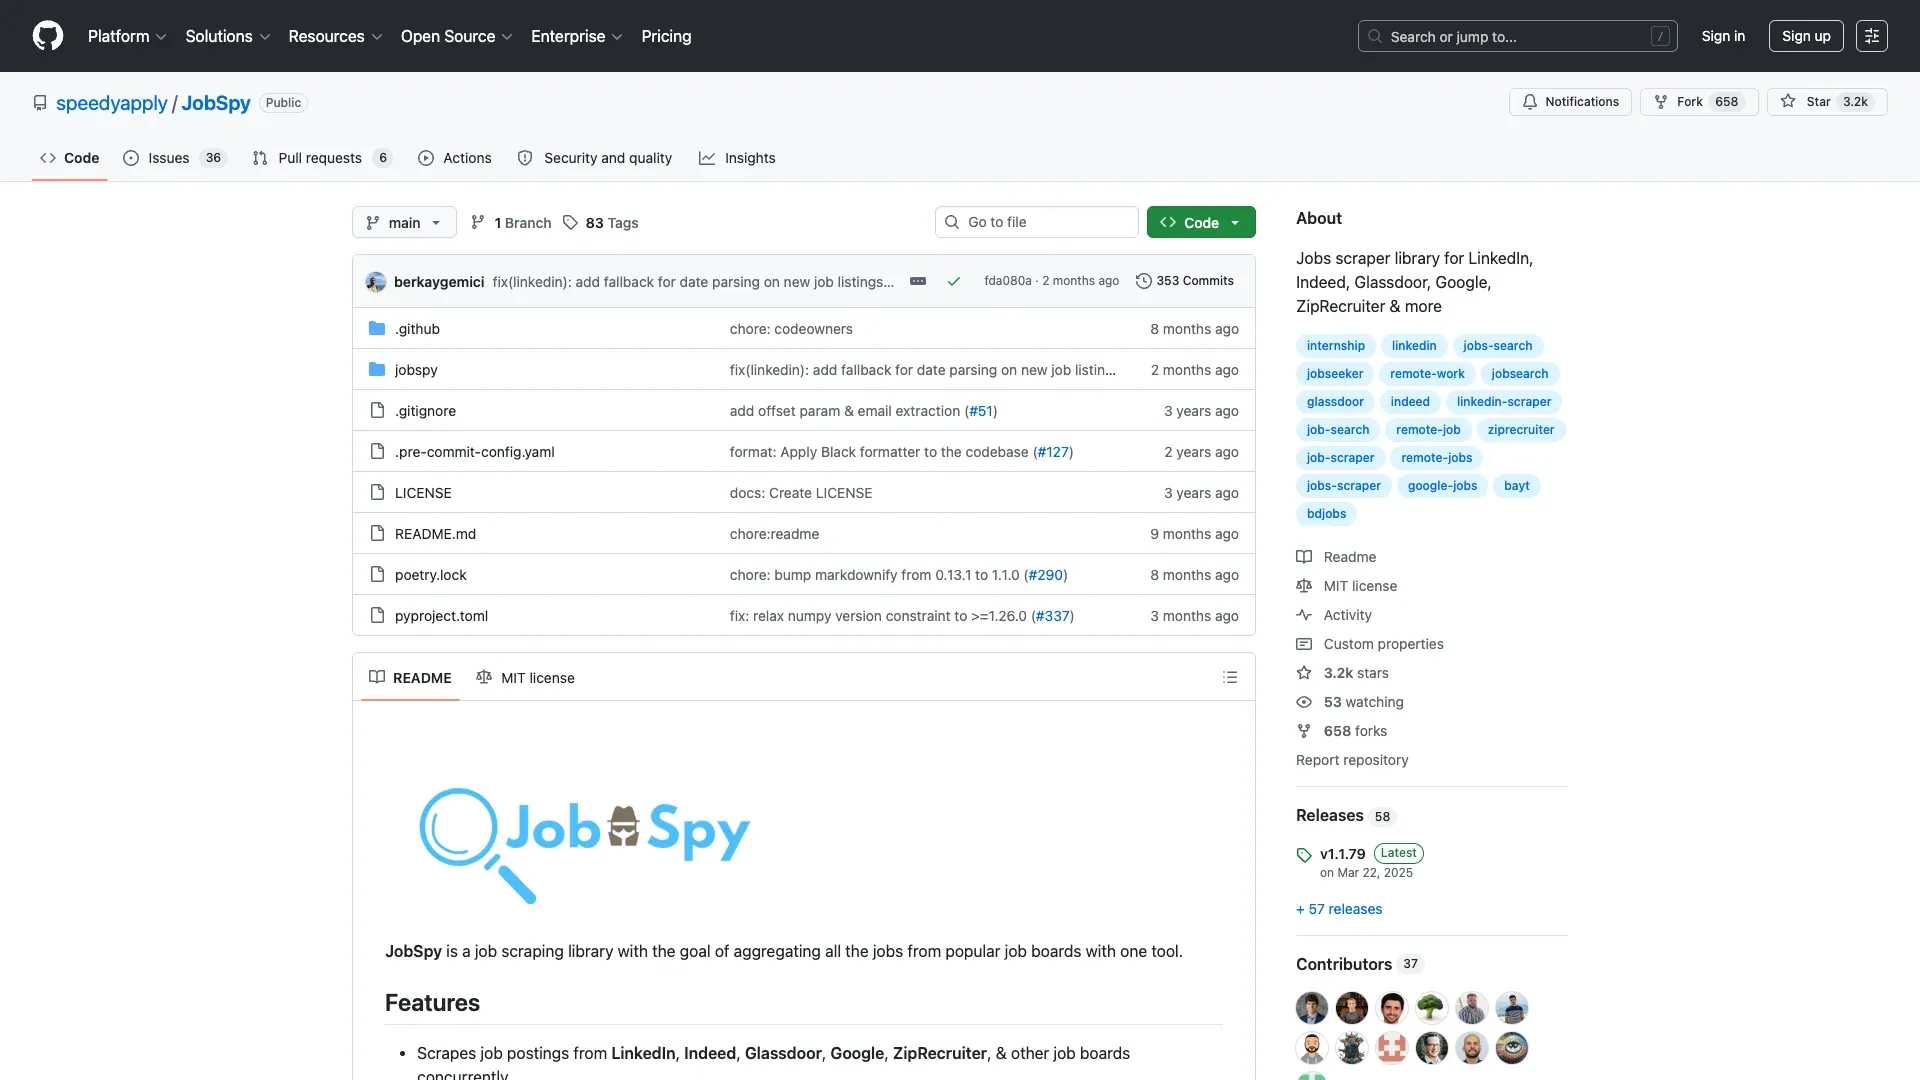 JobSpy is the open-source option worth naming because it's active enough to remain part of the conversation. The GitHub repository shows about 4,020 stars, 58 releases, and support for Indeed, LinkedIn, Glassdoor, ZipRecruiter, Google Jobs, Bayt, and Bdjobs. It outputs to pandas DataFrames and CSV.
- Key features: Multi-board scraping in one script, DataFrame/CSV output, completely free, active community
- Anti-bot handling: Minimal. No built-in proxy rotation, no CAPTCHA solving. You're on your own. Public issues include frequent reports of Indeed blocking or breaking.
- Pricing: Free (open-source). But your proxy costs and debugging time are not free.
The Hidden Cost of "Free"
This is worth spelling out. "Free in dollars" does not mean free in time. If you use JobSpy, expect to spend hours debugging Cloudflare blocks, configuring proxy rotation, and fixing breakage after Indeed layout changes. For a Python developer who enjoys that kind of work, it's a reasonable tradeoff. For a recruiter who just needs 200 job listings in a spreadsheet, it's a terrible deal.
Best for: Python developers who enjoy multi-board scraping and don't mind regular maintenance sessions.
10. Decodo (formerly Smartproxy) — Best Indeed Scraper for Proxy-Focused Users
 Decodo (formerly Smartproxy) now positions itself as a broader scraping platform, not just a proxy seller. Public pages claim 125M+ IPs, 99.99% success rate, and up to 200 requests/second throughput for the Web Scraping API.
- Key features: Rotating residential proxies, web scraping API with JS rendering and CAPTCHA handling, multiple integration methods
- Export formats: HTML, JSON, CSV, PNG, XHR, Markdown
- Pricing: Free starter plan includes about 2K requests, which is unusually generous for testing. Paid plans scale from roughly $0.50 per 1,000 on entry API pricing.
Best for: Teams that think in terms of throughput and request classes. Less beginner-friendly than Thunderbit, less turnkey for Indeed than ZenRows, but a solid middle ground for proxy-savvy users.
Best Indeed Scrapers: Full Comparison Table
| Tool | Type | Coding Required | Anti-Bot Handling | Free Tier | Export Options | Cost per 1K Jobs/Requests | Best For |
|---|---|---|---|---|---|---|---|
| Thunderbit | Chrome Extension | None (2 clicks) | Built-in (cloud + browser) | 6 free pages/mo | CSV, Excel, Sheets, Airtable, Notion, JSON | ~$30/1K rows (Starter) | Recruiters, HR, non-technical |
| Bright Data | Enterprise API + dataset | Low–High | CAPTCHA solving, 400M+ IPs | 5,000 credits/mo | JSON, CSV, NDJSON, API, cloud | ~$1.50/1K records PAYG | Enterprise teams |
| Apify | Actor marketplace | Low (config UI) | Actor-dependent | $5 platform credit | JSON, CSV, Excel, XML, RSS, JSONL | ~$3/1K listings | Low-code users |
| ScraperAPI | API | Yes | Proxy rotation, JS rendering | 5K trial credits | HTML, JSON, text, markdown | ~$4.90/1K protected | Developers on budget |
| Scrapingdog | API | Yes | Stealth mode, CAPTCHA | 200 credits | JSON, HTML, Markdown, CSV | ~$2.00/1K protected | Low-cost API use |
| ZenRows | API + no-code scraper | Low–High | WAF bypass, CAPTCHA bypass | 5,000 credits/mo | CSV, JSON, HTML, Markdown | ~$6.90/1K protected | Anti-bot reliability |
| ScrapingBee | API | Yes | Stealth proxies, JS rendering | 1K calls | JSON, HTML, Markdown, CSV, NDJSON | ~$4.90/1K protected | Developer convenience |
| Oxylabs | Enterprise API + unblocker | Yes | CAPTCHA bypass, 177M+ IPs | 2K results | JSON, HTML, PNG, Markdown | ~$1.15–$1.35/1K | Large-scale proxy infra |
| JobSpy | Python library | Yes (Python) | DIY (minimal) | Fully free | DataFrame, CSV, Excel | $0 (+ proxy costs) | Python developers |
| Decodo | API + proxies | Low–High | JS rendering, CAPTCHA | 2K requests | HTML, JSON, CSV, PNG, Markdown | ~$0.50/1K entry | Proxy-first teams |
Anti-Bot Scorecard: Which Indeed Scrapers Actually Work?
| Tool | Cloudflare Bypass | CAPTCHA Handling | IP Rotation | Reliability Rating |
|---|---|---|---|---|
| Thunderbit (Cloud mode) | ✅ Built-in | ✅ Auto-handled | ✅ Cloud IPs | ⭐⭐⭐⭐ |
| Bright Data | ✅ Advanced | ✅ CAPTCHA solver | ✅ 400M+ IPs | ⭐⭐⭐⭐⭐ |
| Apify | ⚠️ Actor-dependent | ⚠️ Actor-dependent | ⚠️ Add-on | ⭐⭐⭐ |
| ScraperAPI | ✅ Proxy rotation | ✅ Auto-retry | ✅ Built-in | ⭐⭐⭐⭐ |
| Scrapingdog | ✅ Stealth mode | ✅ CAPTCHA solving | ✅ Built-in | ⭐⭐⭐ |
| ZenRows | ✅ WAF bypass | ✅ CAPTCHA bypass | ✅ Premium proxies | ⭐⭐⭐⭐½ |
| ScrapingBee | ✅ Stealth proxies | ✅ Cloudflare tooling | ✅ Built-in | ⭐⭐⭐⭐ |
| Oxylabs | ✅ Advanced | ✅ CAPTCHA bypass | ✅ 177M+ IPs | ⭐⭐⭐⭐½ |
| JobSpy | ⚠️ Breaks frequently | ❌ Manual | ❌ DIY | ⭐⭐ |
| Decodo | ✅ JS rendering | ✅ CAPTCHA handling | ✅ 125M+ IPs | ⭐⭐⭐⭐ |
These ratings combine vendor docs, community evidence, and directional benchmark data — practical editorial judgments, not lab-certified measurements.
Free vs. Paid Indeed Scrapers: What You Actually Get
This is where I see the most confusion in forums. "Free" means very different things depending on the tool.
| Tool | Free Tier | What You Get Free | Gotcha / Limitation |
|---|---|---|---|
| Thunderbit | ✅ Yes | 6 pages/month, free trial = 10 pages, all exports free | Credit-based on paid tiers |
| JobSpy | ✅ Fully free | Unlimited (open-source Python) | No anti-bot; breaks often; requires Python |
| ScraperAPI | ✅ 5K credits | ~5,000 API calls | Protected requests burn 10–25 credits each |
| Scrapingdog | ✅ 200 credits | ~200 requests | Stealth mode costs 10 credits per request |
| ZenRows | ✅ Yes | 5,000 credits/month, no credit card required | Permanent (not time-limited) |
| ScrapingBee | ✅ 1K calls | 1,000 API calls | Serious protected scraping gets expensive fast |
| Apify | ✅ $5 credit | Platform spend | Actor usage can consume it quickly |
| Decodo | ✅ 2K requests | ~2,000 requests | Still requires technical setup |
| Oxylabs | ✅ 2K results | Up to 2,000 results | Product split can confuse newcomers |
| Bright Data | Yes | 5,000 credits/month, no credit card required | Excludes proxy products and Browser API |
The key insight: "free" for Python libraries like JobSpy means free in dollars but expensive in time — you'll spend hours debugging Cloudflare blocks and proxy setup. "Free tier" for tools like Thunderbit means free in both time and money for small-volume use. The tradeoff is real, and I think most non-developers underestimate the maintenance cost of open-source scrapers.
Beyond Job Hunting: 5 Ways Teams Use Indeed Scrapers
Most people assume Indeed scraping is only for job seekers. It's not. Indeed Hiring Lab economist Chris Glynn put it well: "Indeed postings data effectively is the labor market." And that data has business value far beyond finding your next gig.
An NBER paper found that pay-transparency rules increased salary disclosure in postings by about 30 percentage points, making salary extraction from job boards significantly more valuable than even a few years ago. Meanwhile, only 31% of recruiting teams use labor-market data to shape talent strategy, and Payscale reports the average organization now uses 3 salary data sources.
| Use Case | What You Need to Scrape | Best Tool(s) | Why |
|---|---|---|---|
| 💼 Personal job search | Job titles, links, salaries | JobSpy (free), Thunderbit (no-code) | Low volume, budget-friendly |
| 📊 Salary benchmarking / labor market research | Salaries, locations, job levels across thousands of postings | Bright Data, Oxylabs, Apify | High volume, structured output |
| 🏢 Competitive hiring analysis | Employer job postings, headcount trends, full job descriptions | Thunderbit (subpage scraping), ZenRows | Enrich listing data with detail pages |
| 📧 Recruiter lead generation | Company names, locations, contact info from employer pages | Thunderbit (email/phone extractors), Scrapingdog | Extract employer contact data |
| 🌐 Job board / aggregator site | Full listing data, automated refresh | ScraperAPI + Decodo, Bright Data, Apify | Scheduled, high-volume, multi-format export |
Thunderbit's subpage scraping is particularly relevant for competitive hiring analysis. You scrape a listing page, then auto-visit each job detail page to enrich your table with full descriptions, requirements, and benefits. No setup required — the AI handles the field mapping.
From Scrape to Spreadsheet: Exporting and Using Indeed Data
Every competitor article I've read stops at "here's how to get the data." None discuss what happens next.
But users explicitly ask about exporting to CSV, importing to WordPress, and getting data into usable formats. That's a major practical gap.
Here's how the tools compare on the export workflow:
- CSV/Excel export: Thunderbit offers free direct download. JobSpy outputs to DataFrame → CSV with Python. API tools output JSON that you'll need to convert manually or with a script.
- Google Sheets integration: Thunderbit exports directly to Sheets with one click. Most API tools require Zapier or custom scripts to get data into Sheets.
- Airtable/Notion: Thunderbit exports natively to both. Competitors require middleware or manual import.
- CRM import: For sales and recruiting teams pushing employer leads into their pipeline, Thunderbit's structured output (company name, location, contact info) is ready for CRM import. API tools require transformation first.
For non-technical users, the end-to-end workflow — scrape → clean structured table → export to their tool of choice — is the feature that actually matters, not the scraping engine itself. If you've ever stared at a wall of raw JSON and thought "now what?", you know exactly what I mean.
Legal and Ethical Tips for Scraping Indeed
Quick disclaimer: this is operational guidance, not legal advice. Talk to a lawyer for your specific situation.
Indeed's legal terms explicitly prohibit using bots, scrapers, spiders, AI systems, or agentic AI without written permission. Its robots directives restrict many high-value paths for generic crawlers. That said, the data on Indeed is publicly accessible — no login required to view job listings.
Practical recommendations:
- Respect rate limits and avoid bursty collection. Indeed's 60-second rolling window is real.
- Don't scrape login-gated or private data unless you have clear authorization.
- Avoid collecting personal data beyond what's publicly listed and relevant to your use case.
- Don't overload servers. Throttle your requests. Be a good citizen of the web.
The legal landscape around web scraping keeps shifting. When in doubt, err on the side of caution.
Which Indeed Scraper Should You Pick?
After digging into all ten of these tools, my recommendation comes down to four variables: skill level, volume needs, budget, and where you want the data to end up.
- Non-technical users (recruiters, HR, ops) → Thunderbit. Fastest path from Indeed page to usable spreadsheet. No code, free exports, subpage enrichment.
- Budget-conscious developers → Scrapingdog or ScraperAPI. Lowest per-request cost with decent anti-bot handling.
- Enterprise / large-scale → Bright Data or Oxylabs. Best proxy infrastructure, highest reliability, geographic targeting.
- Free and open-source → JobSpy. If you know Python and can tolerate regular breakage.
- Low-code middle ground → Apify Indeed Scraper. Config UI with scheduling and dataset storage.
- Anti-bot priority → ZenRows. Strongest protected-site performance short of enterprise tools.
The "best" Indeed scraper is mostly a function of who you are and what you're trying to do. There's no universal winner — but there is a right tool for your situation.
Try the free tiers before committing. Most of these tools offer enough free usage to validate whether they work on your specific Indeed queries.
And if you want to see what no-code Indeed scraping looks like, give Thunderbit's free trial a spin. I think you'll be surprised how fast you can go from search results to a clean, structured spreadsheet. For more on web scraping without coding or what web scraping is in the first place, we've got you covered on the blog. And our YouTube channel has walkthroughs if you're more of a visual learner.
Happy scraping — and may your 403 errors be few and far between.
FAQs
1. Can you scrape Indeed without coding?
Yes. Thunderbit and Apify both offer no-code or low-code paths. Thunderbit is the easiest true no-code option — it runs as a Chrome Extension directly on the Indeed page, and the entire scrape-to-export workflow takes about 2 minutes with zero code.
2. Is it legal to scrape Indeed?
Indeed's job listings are publicly visible, but its terms of service explicitly prohibit scraping without written permission. Users should respect robots.txt, rate limits, and applicable data privacy laws. This is not legal advice — consult a professional for your specific use case.
3. What is the best free Indeed scraper?
For open-source Python users, JobSpy is completely free but requires Python skills and regular maintenance. For no-code users, Thunderbit's free tier (6 pages/month, free exports) is more practical because it requires no scripting and includes direct spreadsheet exports.
4. How do you handle Cloudflare when scraping Indeed?
Use tools with built-in anti-bot handling. Thunderbit's cloud mode, Bright Data's Web Unlocker, ZenRows' anti-bot API, ScraperAPI's proxy rotation, and Scrapingdog's stealth mode all handle Cloudflare challenges automatically. Indeed's own support docs confirm that Cloudflare-based blocking is part of the current experience.
5. Can you export Indeed scraping results to Google Sheets or Excel?
Thunderbit supports free direct export to Google Sheets, Excel/CSV, Airtable, and Notion. Apify supports export to CSV, Excel, and JSON via its dataset storage. Most API tools (ScraperAPI, ZenRows, ScrapingBee) return JSON or HTML that needs an extra transformation step before spreadsheet use.
Try Thunderbit for Indeed scraping Get Started Free
Learn More



